

To fix an XML sitemap error, open the submitted URL and confirm it returns valid XML. Then check that each listed address is the final, indexable URL you want Google to find. If the sitemap loads and validates, use Search Console’s Page indexing report to investigate individual URLs.
Start with the error in front of you. “Couldn’t fetch” points to access or availability. “Has errors” calls for checking the reported line or URL. A successful sitemap submission tells you Google read the file. Use the Page indexing report to check what happened to individual pages.
Sitemap Errors in Search Console: What Each One Means and the Fix
Open the sitemap row in the Search Console Sitemaps report. Use its status and any listed error details to decide whether to check the server response, repair the XML or correct individual URLs.
| What Search Console says | What it usually means | The fix |
|---|---|---|
| Couldn’t fetch | Google got no usable response: the URL returns 404 or 403, a firewall or bot filter blocks Googlebot, or the file is generated so slowly the request times out. | Open the sitemap URL in a private window and with curl -I: it must return 200 with an XML content type. Check robots.txt and any firewall rule for Googlebot, then resubmit. |
| Sitemap is HTML | The URL serves a web page instead of XML, often a theme’s 404 page or a login screen returned with status 200. | Submit the real XML path (for WordPress usually /sitemap_index.xml or /wp-sitemap.xml) and make sure nothing redirects it. |
| Parsing error / missing XML tag | Broken XML: an unescaped & in a URL, a missing closing tag, or a plugin printing a blank line or PHP notice before <?xml. | Validate the file in an XML validator. Escape & as &, and remove whatever prints before the XML declaration. |
| URL not allowed | The sitemap lists URLs on another host or protocol than the property: www vs non-www, http vs https, a staging domain. | List only absolute URLs on the exact host and protocol of the canonical site, and submit the sitemap in that property. |
| Invalid date | lastmod is not in W3C format, or is empty. | Use YYYY-MM-DD or a full timestamp with time zone, and set it only when the page content really changed. |
| Too many URLs / file size error | One file holds more than 50,000 URLs or is larger than 50 MB uncompressed. | Split it into several sitemaps and list them in a sitemap index; submit the index. |
| Compression error | A .gz file that is not valid gzip, or a server compressing it twice. | Serve plain XML, or recompress the file once and test that it opens. |
A sitemap that shows Success can still be wrong. Errors in the file are only the first layer; the costlier problem is a valid file that lists the wrong URLs. Open the Page indexing report filtered to that sitemap: URLs listed there as redirected, not found (404), excluded by a noindex tag, blocked by robots.txt or as an alternate page with a proper canonical tag are entries that should not be in the sitemap at all. The rest of this article is the rule for what belongs in it.
What a Live XML Sitemap Looks Like
Cross River Tech’s Dallas IT site gives customers a homepage, a company page and a pricing page. The public sitemap lists those same pages using their final HTTPS addresses. Open the pricing page alongside the sitemap and compare the address with its canonical URL.
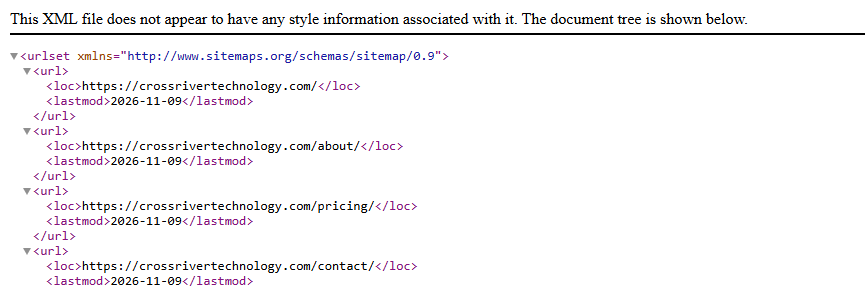
<loc> element. The browser’s message about missing style information is normal for XML. Open the live XML sitemap.| Check | Cross River Tech example | If it fails |
|---|---|---|
| Listed URL | /pricing/ is in the XML under <loc>. | Add the final page to the sitemap generator if you want it indexed. |
| Final destination | The pricing page opens at that HTTPS address. | Replace redirected entries with the final indexable address. |
| Canonical | The pricing page’s canonical points to its own URL. | Check which URL should be canonical and reconcile the sitemap entry. |
Use the same three checks on one page from each section of your site before running a full crawl. Google explains the format and the submission steps in its sitemap guide.
What an XML Sitemap Helps Google Find
- Discovery: URLs in the sitemap get found even when internal links haven’t reached them yet — genuinely valuable for new content, large sites, and deep sections. But discovery is not endorsement: a sitemap entry is a weak hint next to internal links’ votes, which is why sitemap-only orphans still decay — the file gets a page found, not valued.
- Recrawl timing: a truthful
lastmodtells crawlers which known URLs changed — increasingly relevant as crawling gets more selective, and the mechanism behind faster re-indexing of refreshed content. - Canonical signaling, weakly: sitemap inclusion is one of the signals in canonical selection — another reason the file must list only canonical URLs; listing variants casts votes against your own tags.
- Measurement, strongly: Search Console segments the indexing report by sitemap — the coverage numbers for your declared list are the cleanest health metric your index strategy has, and per-section sitemap files turn it into a per-section dashboard.
- Not: a ranking factor, a substitute for internal linking, a way to force indexing of pages quality evaluation declined, or a crawl-permission mechanism (robots.txt governs that; the two files should agree, and robots.txt should reference the sitemap’s location).
The Inclusion Rule and the Exclusion List
Include: every URL that is simultaneously (a) canonical — the page’s own canonical points at itself; (b) indexable — no noindex, not robots-blocked; (c) alive — returns 200; and (d) wanted — you’d be pleased to see it ranking. For a service business that means: the homepage, service pages, honest city pages, articles and guides, the about/contact tier, and indexed category hubs. Exclude, with the reason each exclusion earns its place:
| Excluded URL type | Why it’s a bug in the file |
|---|---|
| Redirected URLs (301/302) | You’re asking crawlers to index an address that forwards elsewhere — wasted fetches and a “submitted URL has redirect” report line; list the destination instead |
| 404s / 410s | Advertising dead pages — the classic post-pruning and post-migration residue when the generator wasn’t updated with the cleanup |
| Noindexed pages | A direct self-contradiction: the file says index this, the page says don’t — the noindex registry and the sitemap exclusions should be the same list |
| Non-canonical variants | Parameter URLs, print versions, and any page whose canonical points elsewhere — each entry votes against your own consolidation |
| Paid landing pages, thank-you pages, utility pages | Deliberately out of search — their sitemap absence is part of the same policy as their noindex |
| Paginated pages (page 2+), thin tag archives | Self-canonical and crawlable, yes — but the sitemap is for destinations you want ranking, and archive pagination isn’t that; main category hubs, where indexed, are |
| Staging, dev, and testing URLs | Should never be reachable at all; their appearance in a production sitemap is an incident, not an entry |
A hand-maintained sitemap is stale by its second month; the sustainable version is generated by the CMS or build process with the exclusion rules encoded: noindexed content types excluded automatically, non-canonical URLs skipped, removed pages dropping out on deletion, lastmod wired to the content’s real modified date rather than the generation run. Most platforms’ SEO plugins do 80% of this by default — the audit work is the remaining 20%: checking which content types the generator includes (tag archives? attachment pages? the classic WordPress media-page leak), confirming lastmod reflects edits rather than regeneration, and encoding your deliberate exclusions (landing-page sections, registry items) in the generator’s settings rather than in someone’s memory.
The Fields: What Matters, What’s Folklore
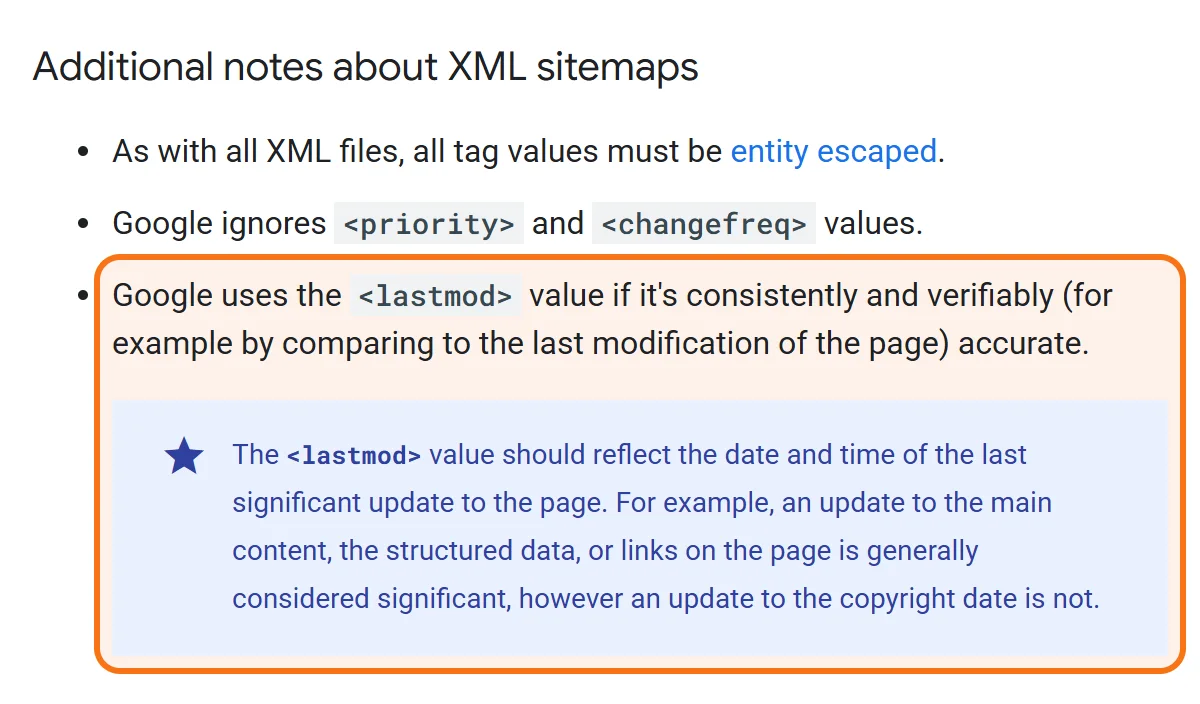
<loc>: absolute URLs, correct protocol and host, matching your enforced canonical format exactly — a sitemap listing http variants of an https site is casting daily votes against your own consolidation.<lastmod>— real, and increasingly load-bearing: Google uses it when it’s consistently accurate and ignores it site-wide when it lies — and the most common lie is structural: generators stamping every URL with the regeneration timestamp, claiming the whole site changed nightly. Wire it to genuine content modification (the same integrity as yourdateModifiedschema), and refreshed pages get recrawled faster — the concrete payoff of the discipline, and half the reason the refresh workflow shows results in weeks.<priority>and<changefreq>— effectively ignored: Google has said for years it disregards both (self-assessed priority was gamed into meaninglessness; changefreq was aspirational fiction). Leaving them in harms nothing; tuning them is effort spent on a dial connected to nothing. Real prioritization lives in internal linking and lastmod truthfulness.- Specialized sitemaps where they apply: image extensions (or image sitemaps) help media-heavy pages’ images get associated and indexed; video sitemaps likewise; news sitemaps are for approved news publishers. For a typical service business, the page sitemap plus image extensions on portfolio-heavy sections covers it.
Structure and Mechanics for Business Sites
- Limits and index files: 50,000 URLs / 50MB (uncompressed) per file; beyond that — or before it, for organization — a sitemap index file references child sitemaps. Even mid-sized sites benefit from segmentation by section (
sitemap-pages.xml,sitemap-articles.xml,sitemap-locations.xml): Search Console reports coverage per child, so a segmented setup shows you at a glance that articles index at 96% while location pages sit at 60% — a diagnosis the monolith hides. - Location and registration: the standard path (or wherever, consistently), referenced in robots.txt (
Sitemap: https://…/sitemap.xml— the line that lets every crawler find it), submitted in Search Console (which is also how you get the reporting), and resubmitted after major changes — migrations, large prunes, structural launches. - Freshness: regenerate on content change (CMS-automatic in most stacks) — a sitemap updated when the site updates is the whole point of the lastmod mechanism. Static sites regenerating on build get this for free if lastmod tracks content dates rather than build dates.
- Format hygiene: valid XML (one malformed entity can invalidate a file — unescaped ampersands in URLs being the classic), UTF-8, correct namespace, and no more creative than the spec: this is a file for parsers, not readers.
With a clean sitemap, Search Console’s page-indexing report (filtered to submitted URLs) becomes diagnostic rather than decorative. ‘Submitted URL has redirect / returns 404 / marked noindex / blocked by robots.txt’: these four are sitemap bugs, full stop — the fix is at the generator (remove or replace the entries), and their persistence signals the generator isn’t enforcing the rules. ‘Duplicate, Google chose different canonical’ on a submitted URL: a consistency conflict — your canonical signals disagree; adjudicate per the canonical guide. ‘Crawled — currently not indexed’ on submitted URLs: not a sitemap bug — the page was found and declined; the diagnosis is quality or linking (the orphan-vs-content fork). ‘Discovered — currently not indexed’: known but not yet fetched — on small sites usually transient; persistent at scale, a crawl-prioritization signal that internal linking should address. The meta-discipline: every status line is either a file fix, a signal-consistency fix, or a content/linking fix — and a sitemap maintained to the inclusion rule makes the sorting instant, which is the measurement dividend the whole discipline pays.
The Quarterly Reconciliation
- Download the sitemap and test its URLs. Flag redirects, errors, noindex and conflicting canonicals. Fix the generator so the errors stay out on the next build.
- Compare it with a site crawl. Look for important, indexable pages that the crawl finds but the sitemap omits. Check whether the generator skipped an entire page type.
- Check the Page indexing report. Filter by sitemap and investigate patterns among pages Google has found. Review internal links and the page itself when the submitted URL is already valid. Use the orphan-page audit to find important pages that have too few routes from the rest of the site.
5 Common Sitemap Mistakes
- Treating submission as optimization. The file aids discovery and measurement; rankings live elsewhere — a submitted sitemap full of junk is worse than none.
- The contradiction entries. Redirects, 404s, noindexed and non-canonical URLs listed — each one a false statement the coverage report will read back to you.
- Lying lastmod. Nightly regeneration timestamps on unchanged content teaches crawlers to ignore your one genuinely useful field.
- Priority-and-changefreq tuning. Hours spent on fields Google discards — the folklore tax.
- Set-and-forget generation. The generator configured at launch, never re-audited — while the site added content types, pruned sections, and migrated twice.
Frequently Asked Questions
Strictly for discovery — barely: a 50-page site with sane internal linking gets fully crawled without one, and Google’s own guidance says small, well-linked sites may not need sitemaps. But the file earns its five minutes of setup on two other grounds. Measurement: submitting a clean sitemap unlocks the per-list coverage reporting — the simplest possible answer to ‘is everything we care about indexed?’ — which is otherwise a manual site: query and guesswork exercise. Recrawl timing: a truthful lastmod gets your refreshed pages revisited faster, which matters exactly when you start doing the content-refresh work that small-site SEO should center on. Since every mainstream CMS generates the file automatically, the real question isn’t whether to have one but whether the auto-generated one follows the rules — the audit points being the same at 50 pages as at 50,000: no junk content types included (media/attachment pages, thin archives), exclusions matching your noindex decisions, lastmod tracking content edits. Five minutes to verify, one Search Console submission, and the smallest site gets the measurement dividend for free.
Work the fetch chain in order. The URL itself: fetch the sitemap address in your own browser — typos in the submitted path, the file living at a different location than submitted, or the CMS having changed the path after a plugin update account for a large share; the file should load as XML, not a 404 page or an HTML error. Access: robots.txt accidentally disallowing the sitemap path, server rules or security plugins blocking crawler user-agents, or auth/firewall layers (common after staging configurations leak into production) all block Google specifically while your browser sees the file fine — test with the URL Inspection tool, which shows what Googlebot experiences. Validity: a malformed file can report as fetch trouble — unescaped ampersands in URLs, encoding issues, an empty file from a failed generation run, or a sitemap index referencing children that themselves 404; run it through an XML validator and open each child. Size and response: files over limits, painfully slow generation (dynamic sitemaps timing out on large sites), or compressed files served with wrong headers. And occasionally the answer is patience with verification: newly submitted sitemaps can show pending or error states transiently — if the file fetches cleanly by hand and via URL Inspection, resubmit and give it a day before deeper surgery.
Apply the inclusion rule per type rather than a blanket archive policy. Main category hubs that you keep indexed (real navigation surfaces, potentially curated, potentially ranking for category-level queries): yes — they’re canonical, indexable, wanted destinations. Paginated continuations (page 2+ of anything): no — they stay crawlable and self-canonical because they’re crawl paths to content, but the sitemap lists destinations you want ranking, and ‘blog page 7’ is nobody’s intended landing experience; the posts themselves are in the file individually, which does the actual discovery work. Tag archives: on most business sites these are noindexed thin slices — and anything noindexed is excluded from the sitemap by rule; the handful of curated tag pages a site deliberately indexes graduate to the same treatment as category hubs. The underlying consistency principle does the deciding in every edge case: the sitemap, the noindex registry, and the canonical setup are three expressions of one index policy — each URL’s treatment across all three should tell the same story, and any URL where they disagree (a noindexed archive in the sitemap, an excluded-from-sitemap page you actually want ranking) is a policy bug regardless of which file technically caused it.
The mechanism: crawlers can’t revisit everything constantly, so they prioritize — and a lastmod they’ve learned to trust lets them skip unchanged URLs and promptly refetch changed ones; Google has stated it uses the field when it’s consistently accurate and disregards it (site-wide) when it isn’t. The payoff is concrete where you do refresh work: a substantively updated article whose sitemap entry honestly reports the change gets re-evaluated in days rather than whenever its routine recrawl arrived — which is why the field is half the delivery mechanism of any content-refresh program. ‘Truthful’ means tracking meaningful content modification: a real edit, a substantive update, a template change that alters the content — not the nightly regeneration timestamp (the structural lie that gets the whole site’s field ignored), not trivial churn (a rotating widget or auto-updating date on the page), and not manual bumping to beg recrawls of unchanged pages (detectable across visits, and the trust once lost applies site-wide). Implementation is where truth is won: wire the generator to the CMS’s content-modified date; on static builds, derive from content-file dates rather than build time; and keep it consistent with your on-page dateModified schema — the two fields testifying identically is exactly the kind of cross-signal agreement the whole technical layer runs on.
Treat the sitemap as a first-class deliverable of the change, not an afterthought that catches up. Immediately with the change: the file must reflect the new reality — removed pages dropped (never left as 404 entries), redirected URLs replaced by their destinations, merged pages’ survivors listed, new URLs added — which happens automatically if the generator is wired to the CMS and manually as a launch-checklist item if not; then resubmit in Search Console to prompt reprocessing (the migration QA checklist has this in its hour-one sweep for good reason). What not to do: leave old URLs in the sitemap ‘so Google finds the redirects’ — Google discovers redirects by crawling its known URL list regardless; the sitemap’s job is declaring the current canon, and stale entries just generate report noise and contradiction signals. Then expect asynchronous settling: the coverage report processes the new file over days-to-weeks; submitted-URL errors (redirect/404 lines) should trend to zero as the reprocessing completes — persistent lines mean entries still leaking from the generator; index counts churn as old URLs exit and new ones enter, which is digestion, not damage. The verification milestone: a quarterly-audit-style reconciliation at plus-four-weeks — sitemap vs crawl vs coverage — confirming the three views agree on the post-change site; agreement there is what ‘migration complete’ actually looks like from the index’s side.
Is your sitemap a canon or a contradiction file?
We’ll reconcile your sitemap against the crawl and the index, fix the generator so the rules enforce themselves, and turn the coverage report into the clean per-section dashboard your index strategy should be measured on.
Get a Technical SEO Audit Explore AEO ServicesCall (346) 244-8617Book a free 30-minute call
Dallas, Texas · no obligation · you speak to Mantas, not a sales desk


